VideoPainter: Any-length Video Inpainting and Editing with Plug-and-Play Context Control
Yuxuan Bian 1, 2, Zhaoyang Zhang 2, Xuan Ju 2, Mingdeng Cao 3, Liangbin Xie 4, Ying Shan 1, Qiang Xu 2
1 ARC Lab, Tencent PCG 2 The Chinese University of Hong Kong 3 The University of Tokyo 4 University of Macau
SIGGRAPH 2025
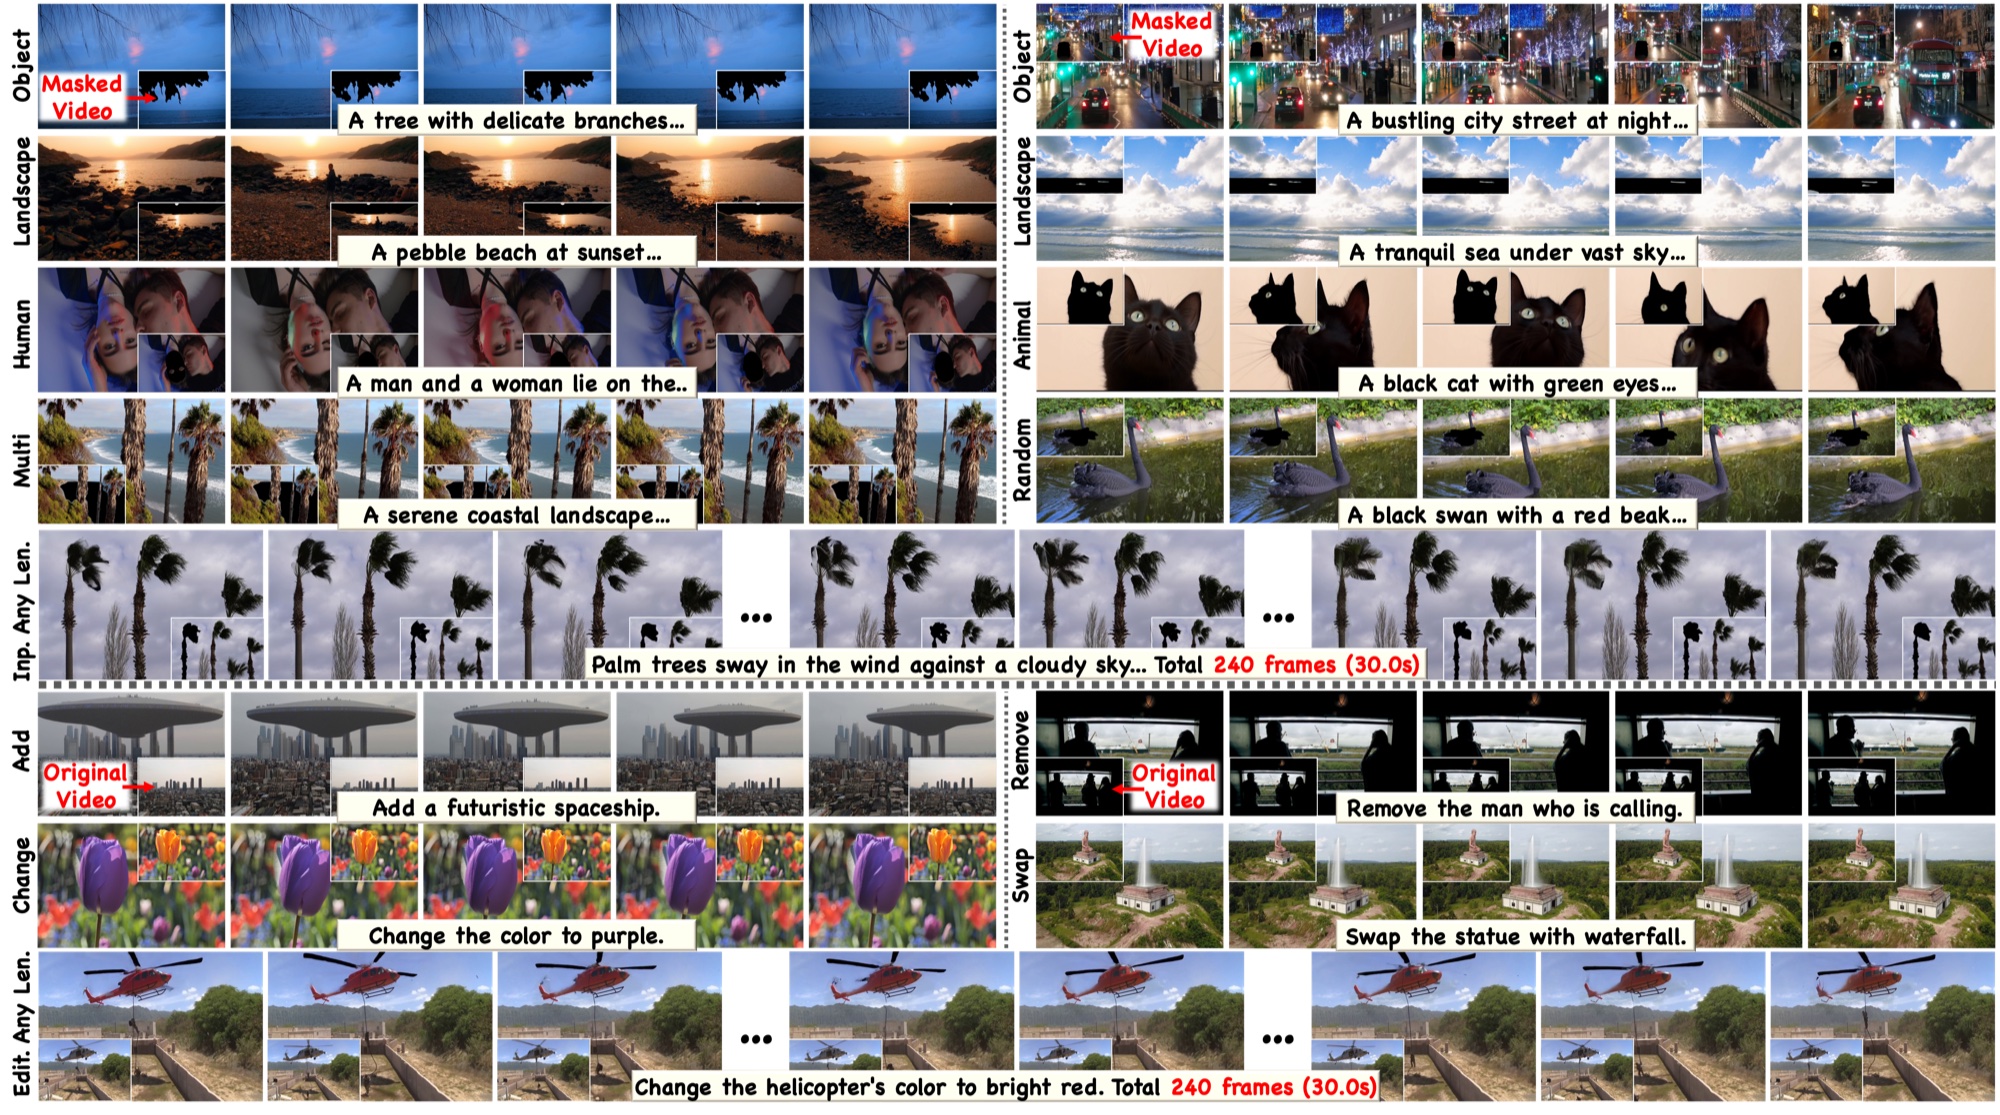
Introduction Video
Click to Play
Method
VideoPainter enables plug-and-play text-guided video inpainting and editing for any video length and pre-trained Diffusion Transformer with masked video and video caption (user editing instruction). VideoPainter contains 1) an efficient and plug-and-play dual-branch framework featuring a lightweight background context encoder, and 2) a ID resampling technique for inpainted region ID preservation.
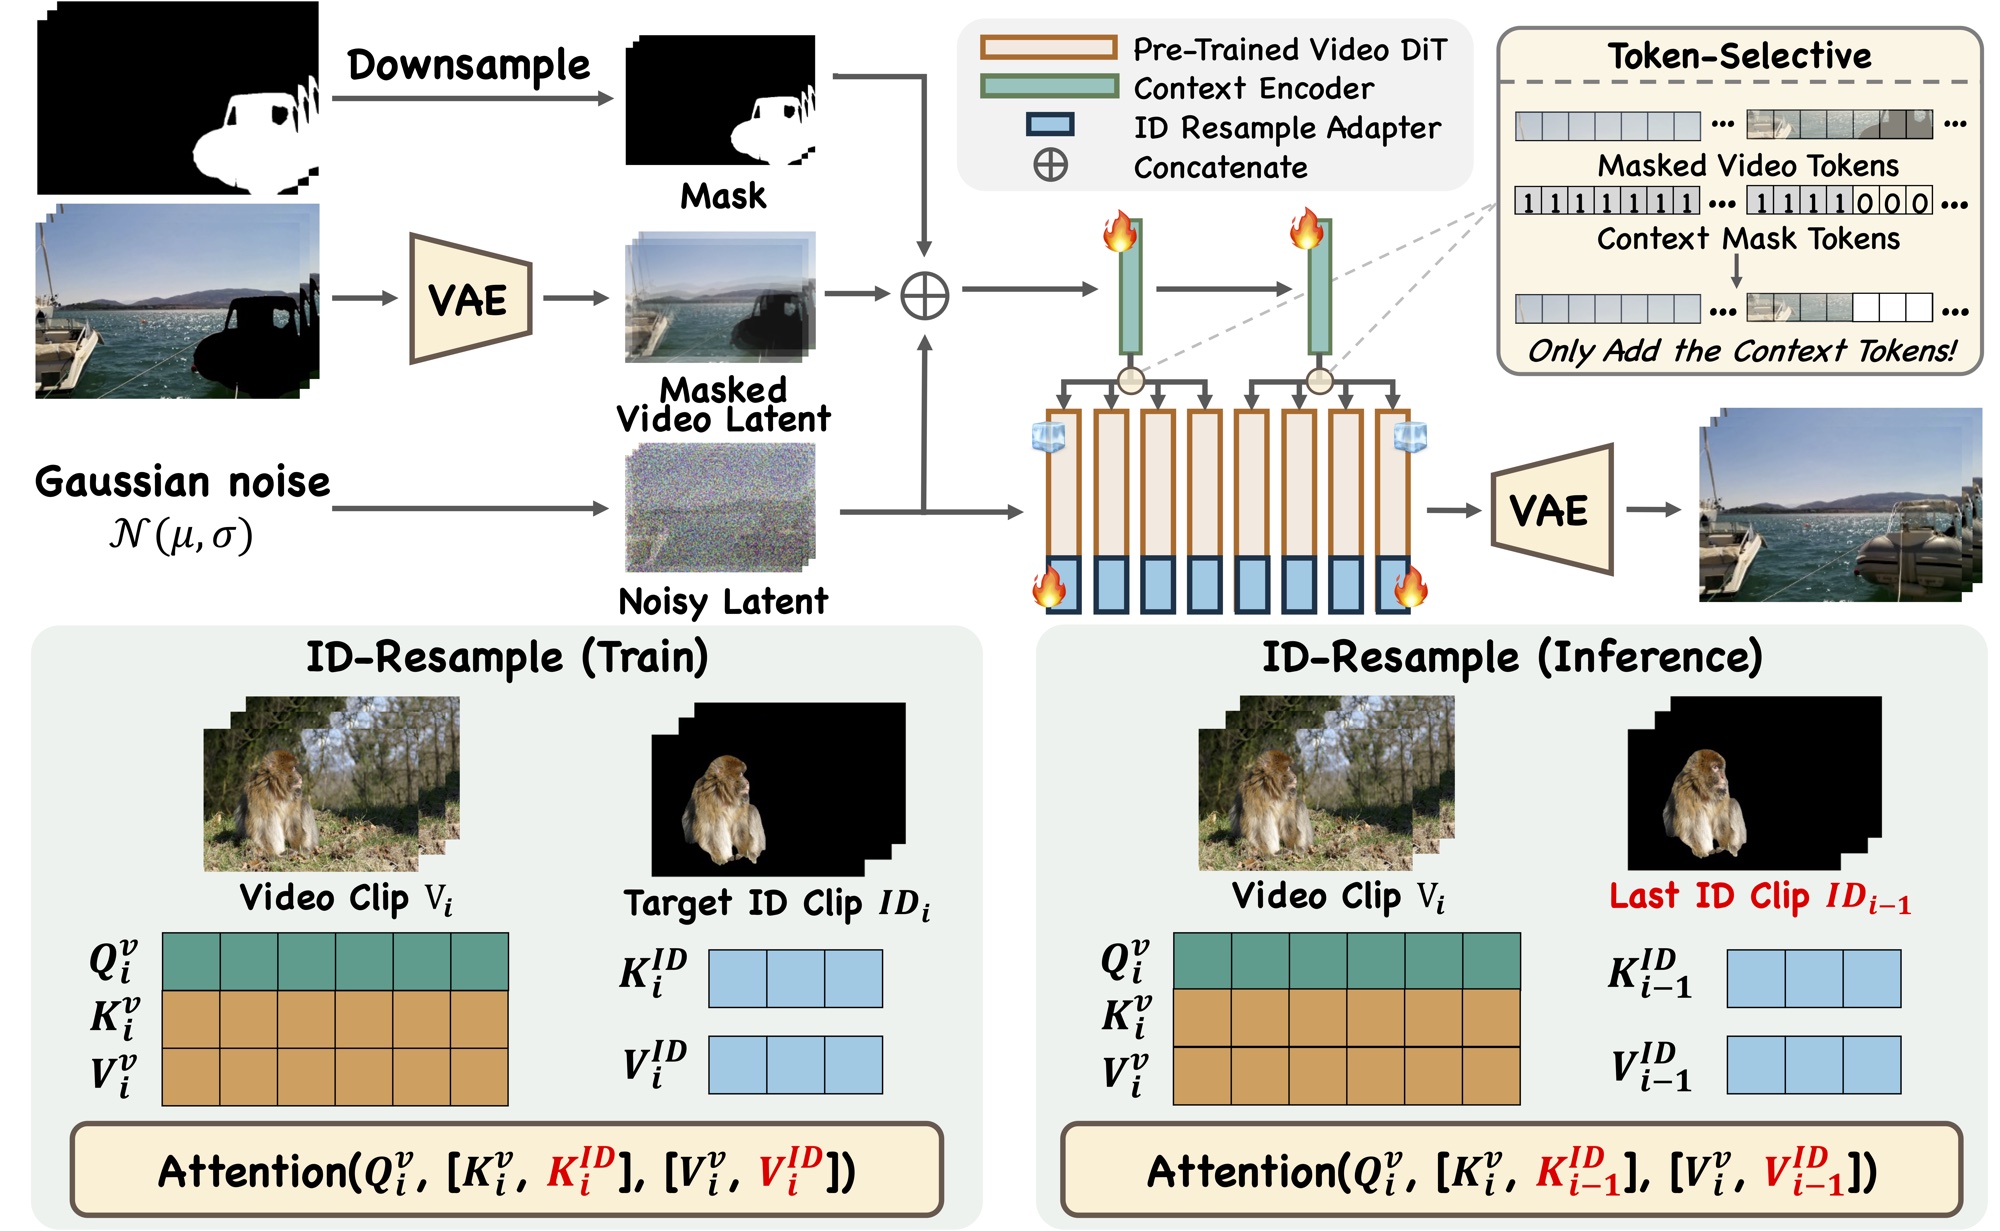
Gallery-Inpaint
Gallery-Edit
Results-Inpaint
Results-Inpaint (Any Length)
Results-Edit
Results-Edit (Any Length)
VPData and VPBench Visualization
More...

Code
View on Github

HF Collection
View on HF
Preprint Paper
View on ArXiv
⭐ Star our github repo if you find our work helpful in your research.
Limitation
As a generative model, VideoPainter may occasionally produce unexpected outputs due to several limitations: (1) Generation quality is limited by the base model, which may struggle with complex physical and motion modeling, and (2) performance is suboptimal with low-quality masks or misaligned video captions. We're actively working on an improved version with enhanced datasets and a more powerful foundation model.
Citation
😊 Consider citing this paper if you find our work helpful in your research.
@misc{bian2025videopainteranylengthvideoinpainting,
      title={VideoPainter: Any-length Video Inpainting and Editing with Plug-and-Play Context Control},
      author={Yuxuan Bian and Zhaoyang Zhang and Xuan Ju and Mingdeng Cao and Liangbin Xie and Ying Shan and Qiang Xu},
      year={2025},
      eprint={2503.05639},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2503.05639},
}